Software project rescue is the work of taking a project that is late, over budget or failing, finding out what is really wrong with it, and getting it back to a state in which it can be delivered. Sometimes it also means deciding, honestly, that parts of it should be stopped. That’s a different thing from adding people to a struggling team, and a different thing again from a consulting review that ends in a slide deck and a list of recommendations nobody is accountable for.
I’ve written this guide for the people who have to make the call – delivery leads, program owners, and partners whose client project has started to go wrong. It covers how to recognize a project in trouble, what to do in the first two days, and what a credible rescue looks like, from the first conversation to a defined end state.
The four signs that travel together
Projects seldom fail along just one axis. By the time anyone actually says the word “rescue” out loud, four conditions are usually present at once. The project is late, and every new estimate is harder to believe than the last one. It’s over budget, and nobody can draw a credible line from the money already spent to the scope that remains. The quality isn’t there – defects keep coming back, people dread releases, and nobody trusts the test evidence. And the team no longer inspires confidence, whether in the eyes of the client or in the eyes of its own leadership.
When all four are present, I have found that the technical problem is seldom the biggest one. Delivery discipline, ownership and honest status reporting tend to fail first, and the code simply records what happened as a result. That’s why a rescue that only repairs the code so often ends up failing a second time.
Earlier warning signs
Those four conditions are late-stage symptoms. The earlier signals usually show up weeks or months before them, while the options are still cheap, and they’re worth taking seriously.
The most familiar one is a project that reports itself as ninety percent complete for several periods in a row, because the last ten percent is where all the unresolved design decisions live. A related sign is a status report that stays green right up until the day it turns red. If amber never appears, nobody is reporting risk at all, only outcomes. Demonstrations that keep getting postponed, or that turn into walkthroughs of slides, deserve the same suspicion, since working software is the one status report that can’t be optimistic.
The schedule tells you a great deal, too. When integration and data migration are planned for “later”, the riskiest parts of most enterprise projects have been pushed to the end, which guarantees that the surprises will turn up at the end as well. Rising reopen rates on defects point to missing tests, unclear requirements or a design that is fighting itself. A project whose architecture only one or two engineers can explain has a key-person risk where its plan should be. And when the client starts asking for more meetings, confidence is usually eroding on the client’s side, well before anyone puts it in writing.
What to do in the first 48 hours
The instinct on a failing project is to do something visible – add people, promise a new date or start a parallel workstream. Most of those moves make matters worse. The first two days are better spent on quieter work.
Stop adding scope, and freeze new requests until there’s an honest picture of what remains. Hold off on adding people for now, because new engineers on a confused project eat up the attention of the few who actually understand it, and capacity should come after the plan, once it’s clear what the plan needs. Get one honest account of where things stand by asking the team, privately, what they believe to be true (as opposed to what has been reported), and treat the gap between the two as a finding in its own right.
Name a single owner on the delivery side, with the authority to make trade-offs, since a rescue without one turns into a committee. Preserve the evidence an assessment will need: the backlog history, estimates, test results, incident logs and decision records. And get an outside view early. The people inside a struggling project are the least able to see its shape, and that has nothing to do with their skill – they have simply been living with it.
What a real rescue looks like
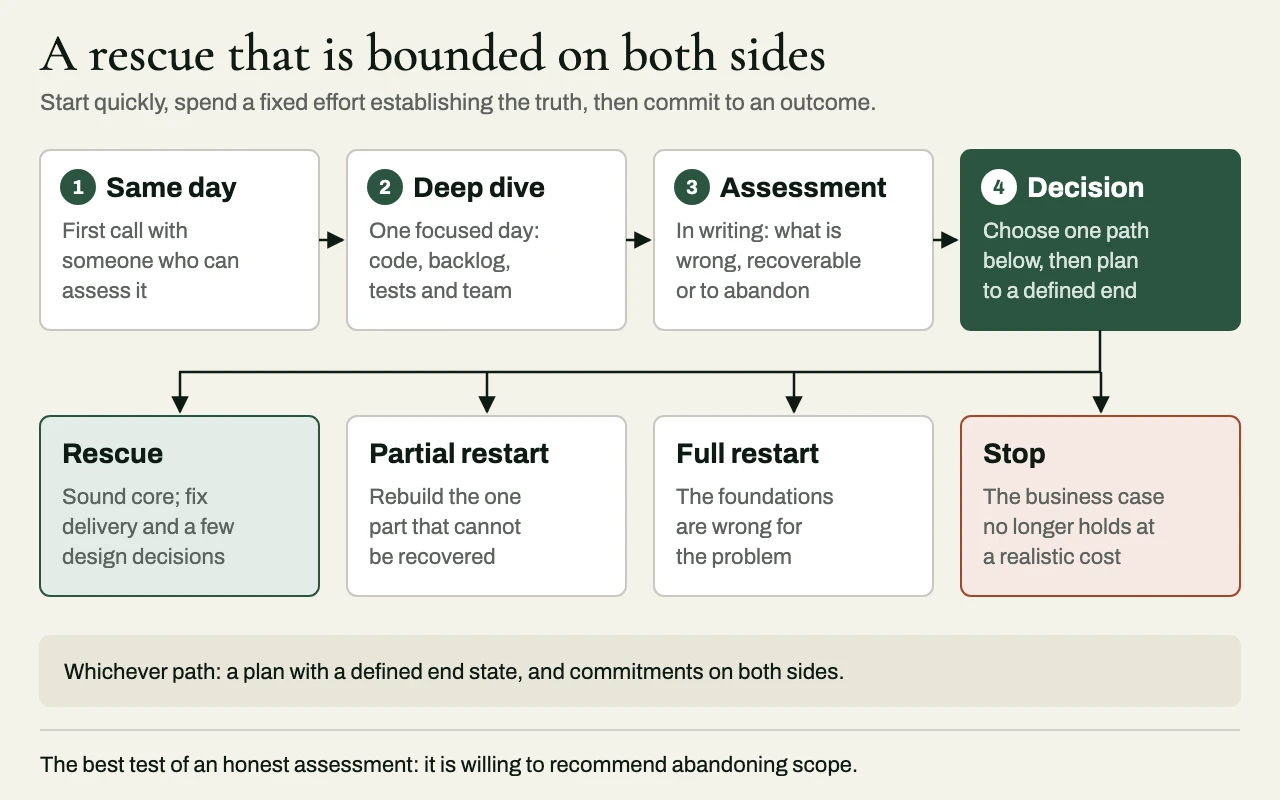
A good rescue is bounded at both ends. It starts quickly, spends a small, fixed amount of effort on establishing the truth, and then commits to specific outcomes. An open-ended engagement that keeps billing until the problem gets bored and goes away is something else entirely.
1. Same-day response
At this stage, speed is part of the remedy. The first conversation should happen on the same business day, with someone who can actually assess the situation – and certainly not by way of a scheduling link for a slot three weeks away.
2. A one-day deep dive
The next step is a single, focused day with the people who know what is really going on. It should cover the code and the architecture, including the integration boundaries and data integrity; the backlog and the estimates, and how they’ve moved over time; the test and release process, and how far anyone trusts it; the team structure, ownership and reporting lines; and what the client says it expects, together with what has already been promised. One day is long enough to find the real constraints, and short enough that nobody has to justify the cost of looking.
3. A written assessment
The deep dive should produce a written assessment of what is wrong, what can be recovered, what should be abandoned, and which paths forward are realistic. A willingness to recommend abandoning part of the scope is, in my view, the best single test of whether an assessment is honest.
4. A rescue plan with a defined end state
If a rescue makes sense, the plan should spell out the concrete conditions that define “done”, map the path from where things stand today to those conditions, and set out what both the rescue team and the client are committing to. A rescue with no definition of done is just more of the same project.
Rescue, restart, or stop?
| Option | Usually right when |
|---|---|
| Rescue | The core architecture is sound, most of the value can be recovered, and the problems are mainly delivery discipline, capacity or a handful of poor design decisions. |
| Partial restart | One component – often an integration layer or a data migration – can’t be recovered, but the rest of the project can. |
| Full restart | The foundations are wrong for the problem, and every fix makes the next one harder. |
| Stop | The business case no longer holds up at the realistic cost. Saying so early is cheaper than saying it late. |
What a rescue actually involves
A rescue has three strands, and every one of them matters. The first is technical assessment and repair – architecture, code quality, integration boundaries, data integrity, test coverage and release mechanics – with a clear line drawn between what should be fixed and what should be replaced. The second is restructuring delivery, which means rebuilding planning, estimation, ownership and reporting so that the status can be trusted and slips show up early, long before the deadline. The third is the team and its capacity. Where capability is the constraint, that means bringing in engineers who have been through rescues before and, when the situation calls for it, building a team at scale.
An example: two years without a delivery
eProxim took over development leadership for a consumer travel booking portal – a troubled program that hadn’t delivered any software in more than two years. Instead of advising from alongside the existing structure, we took over delivery leadership, stood up a 125-person offshore development team, created repeatable processes for architecture, development and QA (so that delivery no longer depended on individual heroics), and put Agile practices in place. The portal software for Air, Car and Hotel shipped.
The lesson applies well beyond travel. The program had talented engineers. What it lacked was ownership, a process people could trust, and someone accountable for the whole thing.
Choosing a rescue partner: questions to ask
- How quickly will someone senior actually look at the situation?
- Is the first step bounded, such as a fixed assessment, or is it an open-ended engagement?
- Is the assessment yours to keep, whether or not you hire them for the rescue?
- Will they recommend stopping or replacing parts of the project if that’s the honest answer?
- Does the rescue plan define end-state outcomes, and responsibilities on both sides?
- If capability is the constraint, can they bring capacity as well as advice?
- Have they restored delivery before by taking ownership of a project (a review on its own doesn’t count)?
- If you’re a partner, can they work under your brand, so that your client sees reinforcements arriving, with no hint of a replacement?
Related reading
If you are a partner with a client project in trouble
A rescue can run entirely under your brand, so your client sees your own firm arriving with reinforcements, and nobody coming in to replace you. eProxim responds on the same business day, starts with a one-day deep dive, and proposes a rescue only with specific end-state outcomes. The details are on our project rescue page, and if what you need is senior ownership of the architecture without a full rescue, take a look at fractional architecture leadership. If the project is already going wrong, today is the useful day to call.