Sooner or later, every webhook integration receives the same event twice. It usually happens in the middle of an incident, when retries are piling up and nobody is watching very closely, and anyone who has been on call knows what comes next – a customer charged twice, an order shipped twice, or a record quietly overwritten with stale information.
Idempotent webhooks are the fix. They’re handlers built so that processing the same event once, twice or ten times leaves things in exactly the same state. In this article, I’ll explain why duplicate and out-of-order events can’t be avoided, go through the patterns that make handlers safe, and set out what the people who send webhooks owe the people who consume them.
Why duplicates are guaranteed
Almost every webhook provider promises at-least-once delivery, and stops short of exactly-once, and they do it on purpose. If a provider can’t confirm that an event was received – because the endpoint timed out, returned an error, or the network lost the response – it will send the event again, because the alternative is risking that the receiver never sees it at all. From the provider’s side, that’s a sensible choice. It does, however, put the whole burden of correctness on the system at the receiving end.
So duplicates come from perfectly ordinary situations. A handler takes too long, and the provider times out and retries an event that has already been processed. An endpoint returns an error after doing part of its work. A deployment restarts a service in the middle of a request. The provider has an incident of its own and re-sends a batch of events, or someone replays events by hand after an outage. Order isn’t guaranteed either. Events travel through distributed systems that retry, so an “updated” event can turn up before its “created” event, and an older state can arrive after a newer one.
The core pattern
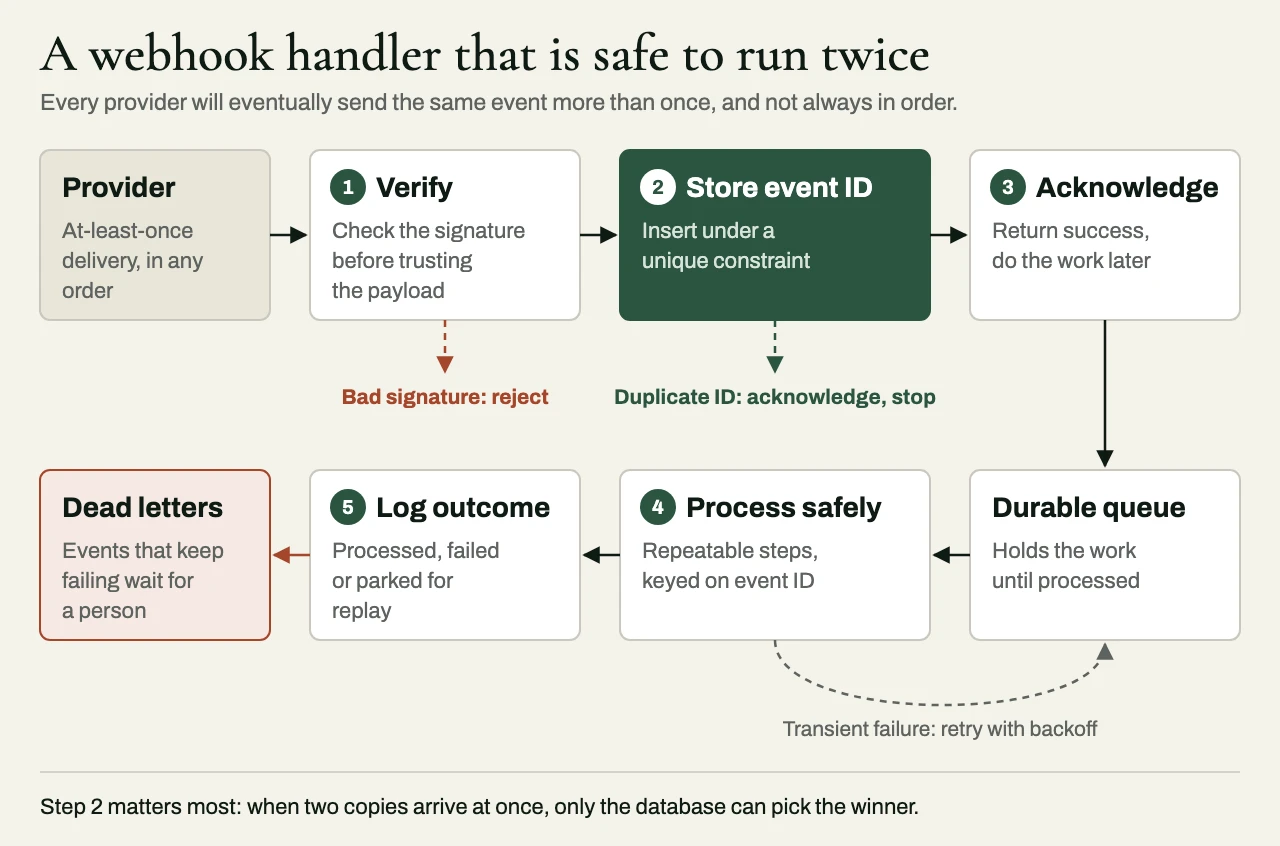
A safe webhook handler does five things, in a particular order. First, it verifies that the event is authentic, checking the signature (or whatever other authentication the provider offers) before it trusts anything in the payload. Then it records the provider’s event ID in a table protected by a unique constraint. If that insert fails because the ID is already there, the event is a duplicate, and the handler acknowledges it and stops.
Third, the handler acknowledges receipt quickly. It returns success as soon as the event is safely recorded, and leaves the real work to run asynchronously from a queue – slow handlers cause timeouts, and timeouts cause retries. Fourth, it processes the event idempotently, by making the business operation itself safe to repeat. “Set the order status to paid” can run twice without harm, which “add a payment” can’t, and where the work creates records, the event ID can serve as their key. Finally, it records the outcome, marking each event as processed, failed or parked, so failures can be retried and looked into.
Of all these steps, the unique constraint matters most. Two copies of the same event can arrive at the same moment on two different servers, and only the database can reliably decide which one wins. No amount of application logic can do that job for it.
Handling out-of-order events
There are two reliable ways to deal with ordering, and plenty of integrations use both. The first is to treat the webhook as nothing more than a notice that something has changed, then call the provider’s API for the object’s current state and apply that. Order stops mattering, and the price is one extra API call. The second is to compare versions or timestamps. If events carry a version number or a timestamp you can trust, the system can store the latest one it has applied to each object, and ignore anything older. What doesn’t work, however tempting it is, is assuming that events arrive in the order in which they happened.
Queues, retries and dead letters
Once events have been recorded and acknowledged, the processing should run from a queue that retries transient failures with backoff – a downstream API that’s briefly unavailable, for instance. Events that keep failing go into a dead-letter queue, where they wait for a person, instead of being retried forever or quietly dropped, and both the size of that queue and the processing lag deserve alerts. The queue should also support replay, which is the ability to re-run the events for a given window of time after an outage or a fix. Because the handlers are idempotent, replay is safe.
Reconcile anyway
Even a well-built handler can miss events, either because the provider never sent them or because the endpoint was down for longer than the provider’s retry window. A periodic reconciliation, which lists recent objects from the provider’s API and compares them with your local records, catches whatever the webhooks missed. Just as important, it shows that the integration is working, so nobody has to take it on faith.
When you are the one sending webhooks
Platforms that send webhooks to partners or customers have obligations of their own, and the same principles apply from the other side. Every event should carry a unique, stable ID, repeated on every retry. Payloads should be signed, and the way to verify them published. Retries should follow a backoff schedule over a documented period, and the documentation should say so plainly. Events should include a version or timestamp, so consumers can handle ordering, and the platform should offer an API for fetching current state, along with an event history consumers can replay from.
Above all, a provider should be honest about its delivery guarantees: at-least-once, with no guarantee of order. Consumers build far better integrations against a provider that tells them the truth about delivery than against one that hints at a precision it doesn’t actually offer.
A client example: duplicate fulfillments under load
An online retailer we worked with ran a weekend promotion that pushed its order volume up about fivefold. Its webhook endpoint received payment-success notifications and called the warehouse API before acknowledging them. At peak, the warehouse API took eight to twelve seconds to answer, the sender timed out and retried, and since the handler kept no durable record of the events it had already seen, a single payment event sometimes triggered two warehouse releases. A warehouse supervisor spotted it first – duplicate pick tickets for orders with the same customer and the same SKUs, but different release timestamps. By the time it was contained, there had been 34 duplicate release attempts, 9 of them had become duplicate pick tickets, and 2 had shipped.
We changed the handler so that it authenticates each webhook, writes the provider’s event ID and raw payload to a durable inbox under a unique constraint, and acknowledges straight away. A separate worker processes the inbox asynchronously and creates the fulfillment command with a business idempotency key made of the order ID and the fulfillment stage, which the warehouse adapter checks before it creates a release. That second key mattered as much as the first, because two different webhook events can describe the same business action, and deduplicating on the event ID alone doesn’t catch them. Failures retry with backoff, and messages that keep failing go to a dead-letter queue for review.
Before go-live, we tested deliberate duplicate deliveries, reordered events, crashes after a side effect and full replays, and a daily job now reconciles paid orders against warehouse releases and shipment confirmations. In the 30 days after the fix, retries kept arriving, as they always will, but none of them produced a duplicate shipment, and every one of them was visible in the processing ledger.
Related reading
- Stripe integration beyond checkout
- Integration reconciliation reports: proving two systems agree
- Shopify ERP integration at peak
Working with eProxim
In the integrations eProxim builds, idempotent processing, retries with dead-letter handling, audit trails and replay come as standard, and nobody has to ask for them as upgrades. We have built event-driven systems in which duplicates carry a real cost, including a telecom usage pipeline designed so that replayed records could never double-charge anyone, and we repair webhook implementations that lose events or process them twice.
Have webhooks that occasionally do things twice? See our enterprise integration services, or start a partner conversation.