You can have a Stripe checkout working in an afternoon. The documentation is excellent, the SDKs are good, and the first test payment goes through almost at once. Oddly enough, that ease is the reason so many Stripe integrations reach production unfinished. The straightforward path is well trodden, and the real engineering is in everything else – authentication challenges, retries, partial failures, webhooks that arrive twice or out of order, refunds, disputes, subscription changes, and the work of proving that what Stripe settled matches what the ledger records.
This article is about the parts of a Stripe integration that come after checkout. They also happen to be the parts that decide whether finance trusts the numbers, and whether a customer ever gets charged twice.
Model the payment as a state machine
A payment isn’t one call that either succeeds or fails. With Payment Intents, it moves through a series of states – it may need a payment method, need the customer to do something (authenticate, for example), be processing, succeed or be canceled. Some of those transitions happen while the customer is still on the page, and others happen minutes or days later.
Two things follow from that. The first is that the browser can’t be the source of truth. A customer may close the tab after paying, or a redirect may fail, so fulfillment should depend on the server-side state of the payment, whether or not the customer ever comes back to a success page. The second is that the merchant’s own order model needs states of its own – pending payment, paid, payment failed, refunded and disputed, say – along with clear rules about which events move an order from one to the next. Setup Intents follow the same reasoning for saving payment methods to be charged later.
Webhooks: the part most often done wrong
Webhooks are how Stripe tells a system what has happened, and they’re also where most production problems start. A sound implementation checks the signature of every event, using the endpoint’s signing secret, before it acts on anything. It responds quickly, acknowledging receipt and handing the real work to a queue, because slow work inside the request leads to timeouts, and timeouts lead to retries. And it’s idempotent – it records the ID of every event it has processed and ignores repeats, since Stripe can, and does, deliver the same event more than once.
A sound implementation also refuses to assume any particular order. Events can arrive out of sequence, so where order matters, the handler should fetch the current state of the object from the API, and ignore the sequence in which the events happened to arrive. It has to be safe to run again, both because Stripe retries failed deliveries for a while and because you should be able to replay events on purpose after an outage. And it’s monitored, with alerts on failed deliveries and processing errors, because an endpoint that has been returning errors for a day is a reconciliation problem that just hasn’t been found yet.
Webhook remediation – repairing an implementation that loses events or processes them twice – is one of the most common pieces of Stripe work partners bring to us. The fix itself is rarely complicated. To be honest, the hard part is usually finding every place where the old behavior has already done damage.
Idempotency on the way in
The same discipline applies to the requests a system sends to Stripe. If a call to create a charge or a refund times out, the caller has no way of knowing whether it went through, and a blind retry can charge a customer twice. Stripe supports idempotency keys on requests for exactly this reason. The right approach is to generate a key tied to the business operation – a particular order’s payment, or a particular refund request – and reuse it on every retry, so a repeated request returns the original result and doesn’t create a second one.
Refunds and disputes
Refunds and disputes are ordinary events in any payment system, and they should be designed into the integration from the start, instead of being handled by hand. A refund may be full or partial, it may fail, and it settles on its own timeline, so the system needs to know which order (and which lines within it) each refund belongs to. Disputes come with deadlines for submitting evidence, which means someone has to be notified, the evidence has to be put together, and the outcome, including the dispute fee, has to be recorded. Both affect the ledger, and refunds, dispute amounts and fees all need to reach accounting linked to the original transaction.
Reconciliation: proving the money matches
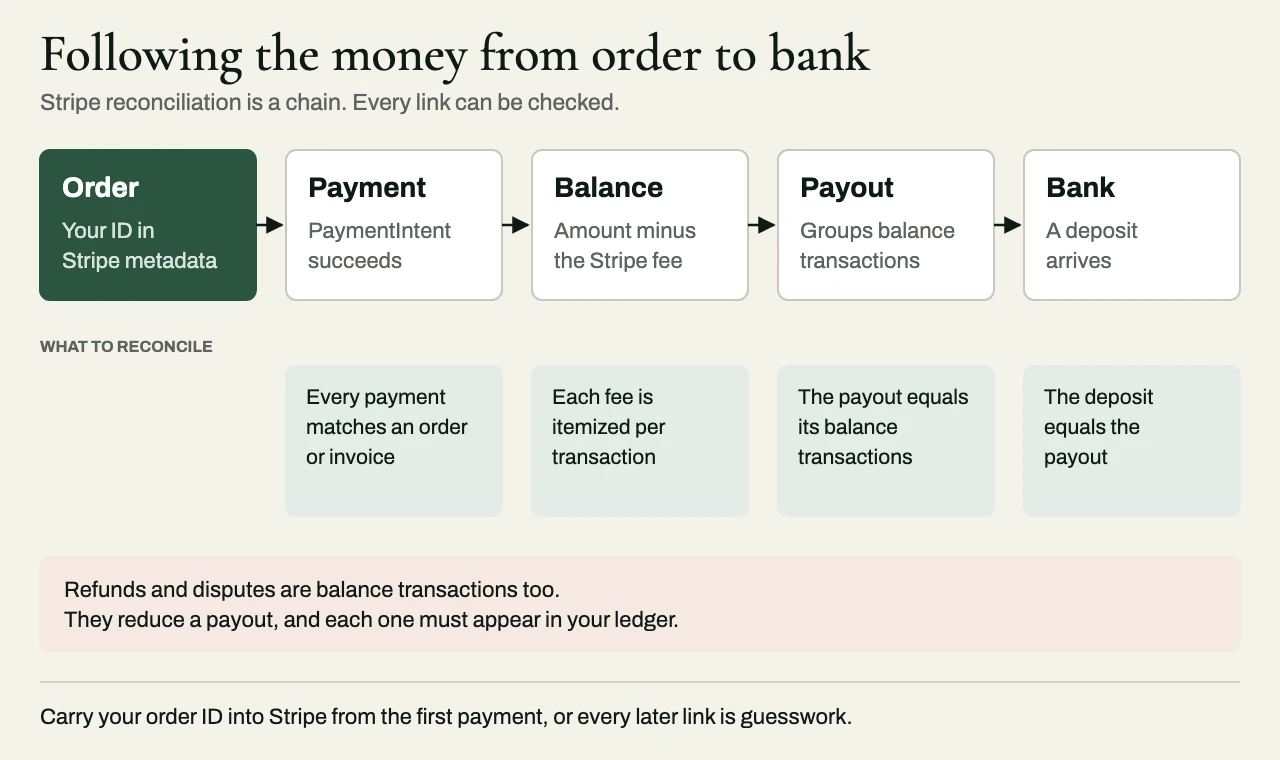
Reconciliation is the part finance cares about most, and it’s the part most integrations neglect. Stripe pays out a net amount – payments, less refunds, disputes and fees, plus adjustments – grouped into payouts that land in the bank account. The ledger, meanwhile, records orders, invoices and revenue. Reconciliation means proving that the two agree.
| Question | Where the answer comes from |
|---|---|
| Which transactions make up this payout? | The Stripe balance transactions associated with the payout |
| What fees were charged, and for what? | The fee details on each balance transaction |
| Does every successful payment match an order or invoice in our system? | Your order IDs, carried in Stripe metadata and matched against your records |
| Does every refund and dispute appear in the ledger? | Refund and dispute objects, matched to accounting entries |
| Does the bank deposit equal the payout? | The payout amount, compared with the bank statement |
The practical requirement is simple. Put your own identifiers into Stripe objects as metadata at the moment you create them, so every Stripe transaction can be matched to a record in your own system. Adding that link afterward is painful. Once it’s in place, reconciling Stripe settlement against an ERP or ledger to the cent becomes a well-defined piece of engineering, which produces a scheduled report and an exception list for someone to work through – and finance no longer has to spend month-end in a spreadsheet.
Subscriptions and Connect
Two areas of Stripe come with edge cases of their own. Where Stripe Billing is the billing system of record, proration, plan changes, trial endings, failed renewals and dunning all generate events that downstream systems have to handle correctly – and the first decision is which system owns the subscription (Stripe, or a separate billing platform), because the integration design follows from that. Stripe Connect, which marketplaces and platforms use, adds payment splits, application fees and payouts to connected accounts, and the reconciliation of all of them. Now the money moves between several parties, and each of them expects their statement to be right.
Migrating to Stripe without interrupting payments
Moving from another processor to Stripe is a payments event, and it’s a mistake to treat it like a data load. Saved payment methods have to move through the processors’ own supported migration processes, without passing through the merchant’s systems at all. Recurring payments mustn’t be missed or doubled during the cutover, and both processors have to be reconciled for the period when they overlap. The cutover should be planned around billing dates, and rehearsed before anyone attempts it for real.
A production-readiness checklist
- Fulfillment depends on the server-side payment state, and never on the browser.
- Webhook signatures are verified, and handlers are fast, idempotent and independent of event order.
- Every request that moves money uses an idempotency key.
- Your identifiers are stored in Stripe metadata on every object you create.
- Refunds, disputes and fees reach the ledger, linked to the original transaction.
- Payouts are reconciled to the bank and to the ledger automatically, with an exception report.
- Failed webhook deliveries and processing errors are monitored, with alerts.
- Test-mode coverage goes beyond successful cards to include failures, authentication challenges, disputes and retries.
A client example: reconciling captures and payouts
The situation
A direct-to-consumer apparel client sold through BigCommerce, with Stripe as the payment gateway. Its Stripe integration posted every successful charge to the ledger as cash received. That sounds reasonable until you remember that a charge and a bank deposit are separate events, and that Stripe pays out a net amount (after fees and refunds) in batches, days later. At every month-end, between 1% and 2% of deposits were left unmatched, and that had gone on for over a year, getting worse as online sales grew.
What we did
We rebuilt the reconciliation around Stripe’s settlement data. A scheduled job matches BigCommerce orders to Stripe charges, the charges to their balance transactions (with fees and refunds), and the balance transactions to payouts and, finally, to the bank deposits.
The edge cases took longer than the matching. The hardest was a multi-item order whose items shipped at different times. We authorized the full amount at checkout and captured per shipment – each capture sent with final_capture=false, and the one for the last shipment with final_capture=true, which releases whatever is left of the authorization. Authorizations expire, so the integration also had to track the age of each one and deal with an expiring authorization before the last shipment went out. One caveat is worth repeating here: multicapture isn’t available for every payment method or every Stripe account, so the design has to check what’s actually enabled, and fall back to a single capture where it isn’t.
The result
The unmatched deposits went to zero. It didn’t happen at once, since each of those edge cases had to be engineered around first, but month-end now closes with every deposit accounted for.
Related reading
- Idempotent webhooks: duplicates, retries and out-of-order events
- Integration reconciliation reports: proving two systems agree
- Zuora implementation partner or integration partner?
Working with eProxim
eProxim doesn’t run a Stripe practice. We work alongside the agencies, platform partners and in-house teams who own the product and the client, and we build the technical layer between Stripe and everything it has to agree with – correct handling of Payment Intents, signed and replay-safe webhooks, Stripe Billing, Connect marketplace flows, processor migrations, and settlement reconciliation against the ERP.
Payments have been part of our integration work since 1997, and idempotent processing is a default in everything we build. On one telecom engagement, we designed a usage-rating pipeline that handled 1.4 million events per second, built so that duplicate or replayed records could never cause a double charge. The same principle runs through every payment integration we touch.
Bring us the Stripe work you’d prefer not to hire for. Take a look at our Stripe partner page, or start a partner conversation.