In most businesses, the useful applications of AI have very little to do with conversation. They’re process-bound work – reading a document and pulling out what matters, deciding which path a case should take, reconciling two records that disagree, or drafting a response that a person then approves.
An AI agent doing this work has to act on real systems, such as the ERP, the CRM and the ticketing platform, and that’s the point at which AI agent guardrails stop being a philosophical topic and become an engineering requirement. An agent that can act needs boundaries it can’t reason its way past, and it needs a record of everything it did.
A worker with one job
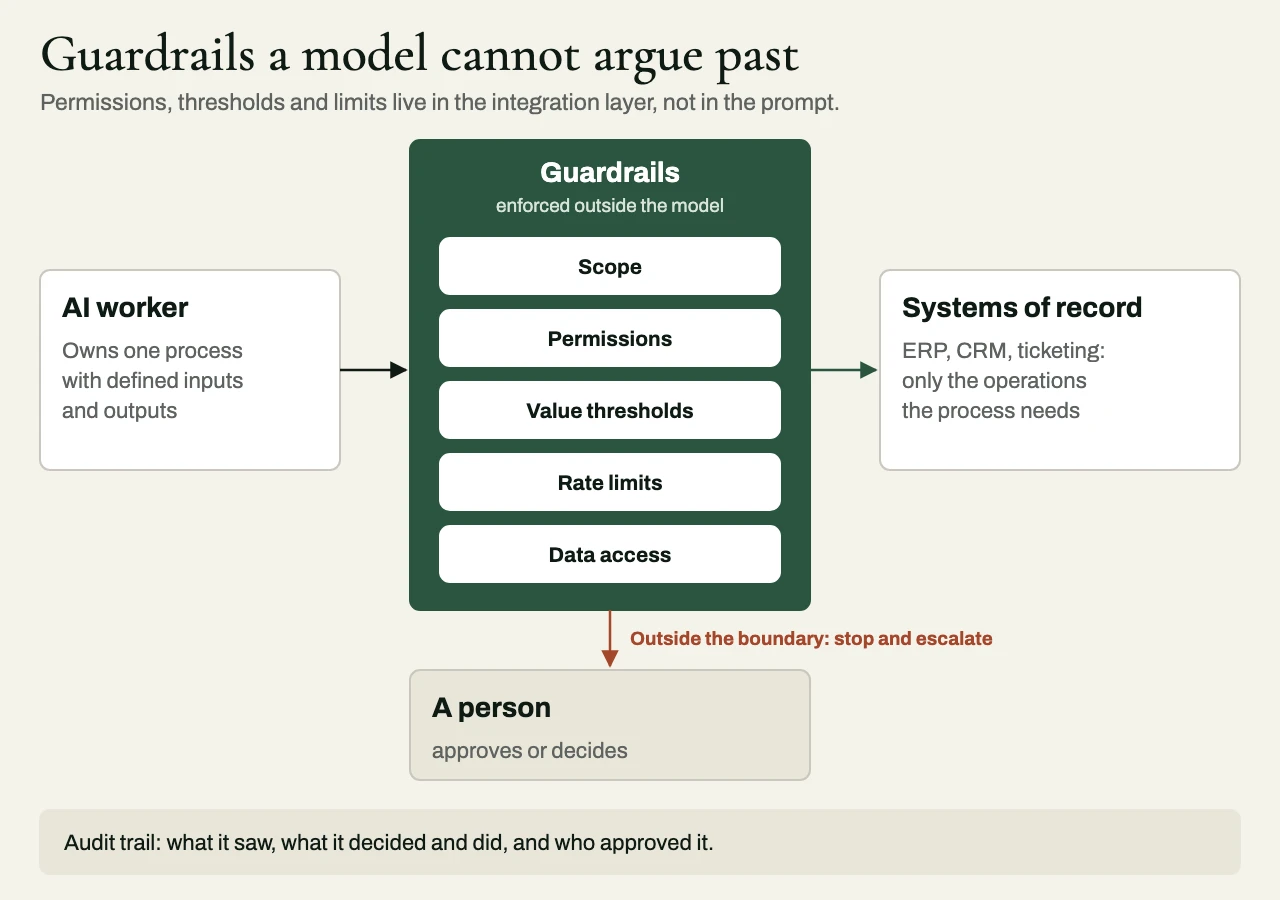
The first guardrail is a design choice: build a bounded process owner, and resist the pull toward a general-purpose assistant with broad access. A bounded worker owns one process, with defined inputs, outputs and conditions for success. It gets only the tools and data that process needs, and it knows both what a correct outcome looks like and what it has to hand over to a person.
A general-purpose agent with vague access to everything is harder to test and harder to secure, and it’s impossible to explain to an auditor. To be honest, I think most of the risk people associate with AI agents is really the risk of that second design.
The guardrails that matter
| Guardrail | What it constrains | Example |
|---|---|---|
| Scope | Which process and which records the worker handles | Only supplier invoices for one entity |
| Permissions | Which systems and operations it can use | Can create a draft credit note, can’t post it |
| Value thresholds | The size of action it can take on its own | Auto-approves matches within a set tolerance; escalates larger differences |
| Rate limits | How much it can do in a period | A cap on actions per hour, so a fault can’t cascade |
| Data access | What it can read, and what leaves the boundary | No personal data sent outside approved services |
| Escalation rules | When it must stop and hand off | Unrecognized document types, conflicting records, low confidence |
Two principles apply to all of them. The first is that guardrails have to be enforced outside the model. Permissions, thresholds and rate limits belong in the integration layer and in the systems’ own access controls, and never in a prompt, because a model can talk its way around a prompt, while an API permission simply refuses the call. The second is that the worker should fail closed. Anything that falls outside its boundary stops and escalates, and the worker doesn’t get to improvise.
Human checkpoints, calibrated to risk
Not every action needs approval, and requiring approval for everything defeats the purpose of automating the work in the first place. So autonomy should be matched to consequence. Where an action has little consequence and is easy to reverse, the worker can act and record what it did. Where the consequence is moderate, the worker prepares the decision, and a person approves it. Where the consequence is high, or the action can’t be undone, a person decides, and the worker’s job is to assemble the evidence.
That calibration should be written down and agreed with whoever carries the risk – usually finance, operations or compliance – before anything is built. It’s far easier to win a risk function’s confidence by showing it the boundaries in advance than by explaining them after an incident.
Audit trails
Every action, input, decision and output should be recorded, and it should be possible to query them: what the worker saw, what it decided and why, what it did, and who approved it, if anyone did. When an auditor, a regulator or a finance lead asks what happened to a particular record on a particular date, there has to be an answer. An automation that nobody can inspect is really just a stream of unrecorded decisions, made around the clock, and I wouldn’t call that a capability.
Evaluate before autonomy widens
Guardrails are only as good as the evidence that the worker behaves well inside them, and that evidence has to be gathered before its autonomy is extended. A disciplined sequence looks like this:
- Evaluate against held-back cases with known correct outcomes, and measure accuracy and escalation rate.
- Start with a person approving every action, and compare the worker’s proposals with what that person actually decides.
- Loosen gradually as the track record justifies it, one category of action at a time.
- Keep monitoring after go-live – accuracy, escalation rate, exceptions, and drift as the inputs change.
Choosing a first process
The best first candidates are processes that are frequent, governed by rules, done by hand today and measurably expensive, which in practice usually means exception handling, reconciliation, case triage, document processing and data enrichment. Processes that are none of those things make poor first candidates, however interesting they sound, because there’s neither enough volume to learn from nor a clear cost to measure success against.
A client example: an invoice dispute worker
One of our clients, an industrial equipment distributor, keeps its customer notes in Salesforce and its invoices and credits in NetSuite (a common NetSuite Salesforce split). We built a Python-based worker for its accounts receivable disputes. It reads disputed invoices and the account notes, gathers the supporting transactions, and proposes credit memos through a restricted tool gateway, which decides what actually reaches NetSuite.
A customer disputed three invoices totaling $47,800, and the account manager’s note said the customer expected credits and that the account manager had agreed to review them. The model read that as approval and proposed a full credit. The gateway blocked it, because no finance approval record existed, the dispute was still under review, and the worker had no authority to set an approval status. The finance operations manager noticed four rejected attempts on the same dispute within eleven minutes, and when engineering looked at the trace, it turned out the model had been treating phrases like “we’ll take care of it” as authorization.
The rejection log then became a diagnostic tool. Over two weeks it recorded 186 blocked attempts: 91 lacked approval, 38 exceeded the approved amount, 29 were duplicate retries, 17 pointed at the wrong customer or invoice, and 11 targeted closed periods. We made three changes. The model lost any ability to declare approval, the gateway began requiring a verified approval record and amount, and business-rule failures stopped being retried. We also narrowed the NetSuite integration role, so that a defect in the gateway can’t hand out unrestricted accounting powers.
In the end, finance authorized a $6,200 credit for a shipment discrepancy it confirmed, and the remaining $41,600 stayed collectible. In the 30 days after the changes, the log recorded 20 approval-related rejections and 2 duplicate attempts, and no unauthorized credit was posted. The worker still investigates and recommends, and the authority to grant a credit stays with finance.
Related reading
- Integration reconciliation reports: proving two systems agree
- Idempotent webhooks: duplicates, retries and out-of-order events
Working with eProxim
eProxim builds AI workers that run process-bound workflows with bounded scope, explicit guardrails, human checkpoints and full audit trails. They act through the same APIs, middleware and event pipelines we build for integration work, so they operate on the real systems of record, and never on exports, and they can be delivered under a partner’s brand.
Have a process your client repeats a thousand times a month? See our AI automation services, or start a partner conversation.